The day AWS went dark
On October 20, 2025, AWS experienced a large-scale outage that disrupted services across the globe. Websites, mobile apps, and entire infrastructures went offline within minutes. The incident originated in AWS’s US-EAST-1 region, highlighting how dependent modern businesses have become on centralized cloud systems and why resilience in architecture is no longer optional.
.avif?2026-08-24T09%3A16%3A10.228Z)
Introduction
What happened and when?
In the early hours of the morning, AWS users began reporting connection failures and service disruptions. The issue originated in one of Amazon’s largest and most interlinked data centers. Within minutes, it affected global traffic routes, bringing down platforms like Snapchat, Fortnite, and even parts of Amazon’s own services. AWS confirmed that increased error rates and latency were caused by a fault in its load balancing and health monitoring subsystems, which led to cascading failures across multiple internal services.
.avif?2026-08-24T09%3A16%3A10.219Z)
What happened
Why did it happen?
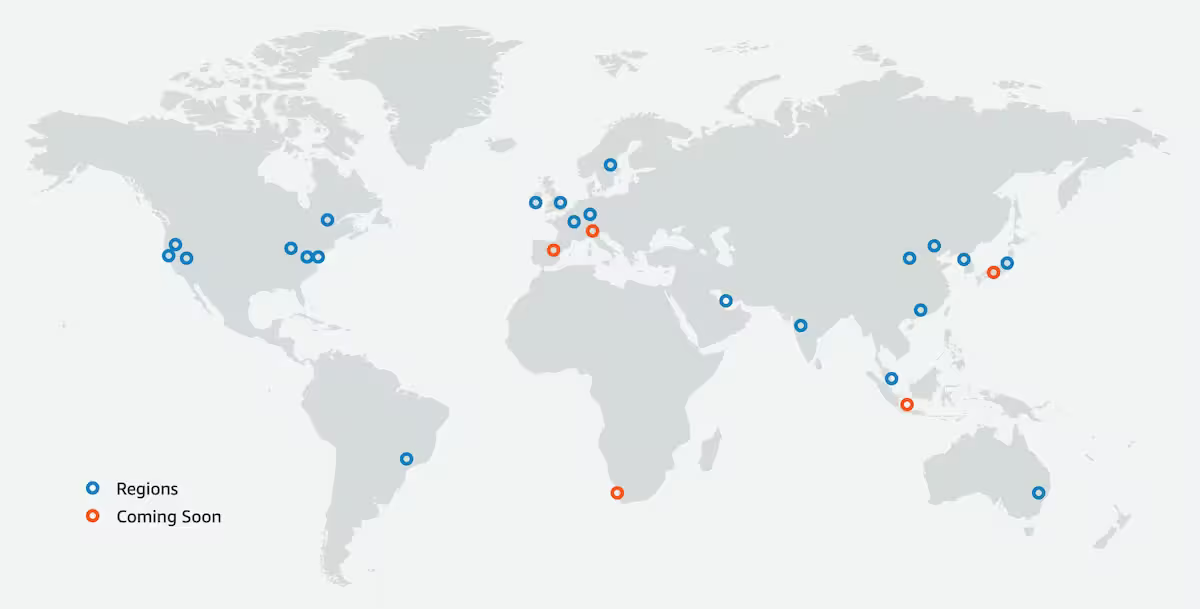
At the core of the incident was a failure in AWS’s internal network load-balancing system, which distributes incoming traffic across servers to keep applications running smoothly. When that subsystem malfunctioned, it triggered a domino effect - health checks began failing, routing tables became unstable, and dependent services started timing out.
Because many AWS services rely on shared internal components, the disruption quickly spread across the platform. Even applications hosted in other regions experienced intermittent slowdowns, since global DNS and authentication systems were impacted.
How higroup stayed online
Impact on higroup
While the outage disrupted many global platforms, higroup’s systems remained fully operational. Our infrastructure majorly runs on AWS’s EU region, which was unaffected by the incident. By design, we separate environments by geography and purpose - ensuring that a disruption in one region never cascades into another.
This regional isolation is paired with redundant architecture: automated backups, independent service clusters, and failover mechanisms that keep core systems responsive even when external dependencies slow down. It’s part of our broader commitment to resilient engineering - designing for failure, so clients stay online when the cloud doesn’t.
Why did it happen?
How to prevent issues like this?
Cloud outages are inevitable, but downtime doesn’t have to be. The key lies in architecture designed for resilience, not convenience. Systems should anticipate regional or service-level disruptions and be able to redistribute loads automatically when a failure occurs. At higroup, we design infrastructures that leverage multi-region redundancy, auto-scaling groups, and load balancers that reroute traffic to healthy zones in real time. For mission-critical platforms, we also apply disaster recovery environments across multiple cloud providers AWS, Azure and GCP.
Lessons for software teams
True resilience is built on preparation, not reaction. Design systems with geographic and infrastructure redundancy, ensuring multiple regions or availability zones can take over when one fails. Establish and rehearse clear failover procedures so they can be executed instantly when needed. Combine this with strong monitoring not just for uptime but for the performance of every service and dependency. Knowing when and where failures occur allows teams to respond fast, limit disruption, and maintain user trust. In short, resilience isn’t just about avoiding failure - it’s about being ready for it.
Lessons
Beyond the outage: Building resilience that lasts
Cloud outages will happen again - it’s not a question of if, but when. The difference lies in how prepared teams are to respond. Each incident, like the AWS downtime, reminds us that resilience is a mindset, not just a configuration.
At higroup, we see reliability as a continuous process — one built on smart architecture, observability, and preparation. From multi-region setups to proactive monitoring and tested failover plans, our goal is to make downtime invisible to users.
Because in the end, the real test of great engineering isn’t avoiding failure - it’s how quickly you recover from it.